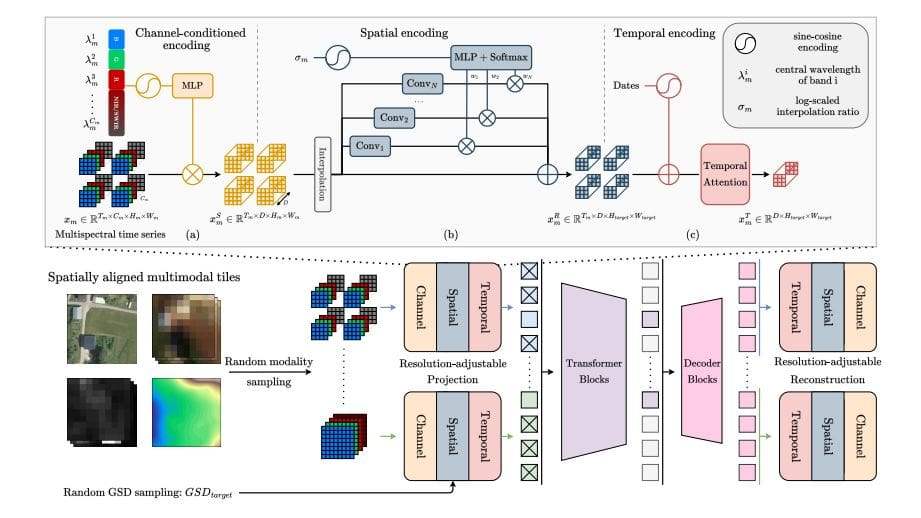
Bold claim: RAMEN reframes how Earth-observation data is analyzed by letting the resolution itself be adjustable, so disparate data sources finally speak the same language. But here's where it gets controversial: does letting users dial in detail always lead to better results, or can it blur crucial nuances when misused? The authors tackle these questions by introducing RAMEN, a resolution-adjustable multimodal encoder designed to fuse information from heterogeneous Earth-observation sensors into a single, coherent representation. The core idea is simple yet powerful: treat spatial resolution as a controllable output parameter, balancing precision against computational cost while preserving cross-modal compatibility. This approach enables analysts to tailor analyses to their needs without ditching data from higher- or lower-resolution sources, which often come from different sensors or platforms. RAMEN’s core claim is that such a unified representation improves performance on multi-sensor tasks and scales across varied datasets.
RAMEN’s performance across resolutions
The paper assesses RAMEN in semantic segmentation tasks across multiple datasets and resolutions. Semantic segmentation assigns a class to every pixel, with performance measured by mean Intersection over Union (mIoU) — higher is better. RAMEN was tested at different Ground Sampling Distances (GSDs), where a lower GSD means higher input resolution. The model’s performance was compared to other methods like DOFA and TerraMind, considering both accuracy and computational cost.
Findings show a clear trade-off: as resolution increases, performance often improves, but so does computational demand. On the CropTypeMapping, South Sudan dataset, RAMEN reached a peak mIoU of 58.19% at a GSD of 80, while TerraMind-B achieved the best overall score of 55.80%. For SpaceNet 7, RAMEN hit 60% mIoU, and for the AI4SmallFarms dataset, RAMEN achieved 38.78% mIoU at a GSD of 10, surpassing TerraMind-B’s best of 28.12%. On the HLS BurnScars or similar datasets, RAMEN demonstrates the ability to maintain strong performance across a range of resolutions, underscoring the importance of selecting an appropriate GSD to balance accuracy with computational cost. Overall, RAMEN shows competitive results across datasets and resolutions, though effectiveness can vary with the data type and the desired level of detail.
RAMEN’s architectural approach
RAMEN is a pioneering resolution-adjustable multimodal encoder crafted to overcome the challenges of processing diverse Earth-observation (EO) data. It learns a shared visual representation across inputs that differ in spatial, spectral, and temporal resolution, enabling coherent analysis within a single latent space. A standout feature is the explicit treatment of spatial resolution as a controllable output parameter, letting users decide the level of detail and optimize the precision–cost trade-off.
To achieve this, RAMEN treats modality and resolution as primary input features and projects each into a common latent space shaped by their characteristics. A critical component is an adjustable spatial resampler that aligns heterogeneous inputs by mapping them to a target GSD. During training, the target GSD is randomly selected to promote generalization across scales and prevent bias toward any single resolution. A temporal attention module captures dependencies over time, enhancing robustness for time-series or sequential EO data.
RAMEN is trained on a large, multimodal EO corpus using a self-supervised masked image modeling strategy. Regions are randomly masked and then reconstructed, pushing the model to learn meaningful representations from partial information. All learnable parameters are shared across modalities, maximizing adaptability to diverse datasets. This design enables RAMEN to outperform larger state-of-the-art models on the PANGAEA benchmark, evidencing its effectiveness across multi-sensor, multi-resolution tasks.
Implications and potential applications
RAMEN’s ability to adjust resolution while fusing multiple sensors promises broader applicability, from land-cover mapping and flood detection to wildfire monitoring and beyond. The model’s efficiency—achieving strong results with a lighter ViT-Base encoder—suggests practical deployment possibilities where computational resources are limited. Importantly, RAMEN’s demonstrated generalization across different sensors and resolutions points to a scalable foundation for versatile Earth-observation analytics that can adapt to evolving sensor configurations and application needs.
In short, RAMEN offers a flexible, efficient, and robust solution for multi-sensor EO data analysis, enabling coherent interpretation across heterogeneous data while providing explicit control over the balance between detail and computation. This balance is critical as Earth-observation programs continue to accumulate data at increasing variety and volume.
For further reading, see RAMEN: Resolution-Adjustable Multimodal Encoder for Earth Observation, with accompanying materials and ArXiv preprint at https://arxiv.org/abs/2512.05025.